www.usa-automation.net
26
'26
Written on Modified on
Humanoid Robot Sensor Fusion Architecture with Low-Latency Processing
Hexagon Robotics integrates NVIDIA Holoscan into the AEON humanoid to eliminate compute bottlenecks and simplify perception cabling.
hexagon.com
In industrial automation and unstructured operating environments, multipurpose humanoid robots require comprehensive spatial intelligence to map facilities, manipulate components, and construct real-time digital twins. Hexagon Robotics addresses these demands by deploying the NVIDIA Holoscan edge computing framework aboard its AEON humanoid, replacing a resource-intensive legacy sensor pipeline with a centralized, pre-processed architecture designed to scale perception throughput without overloading primary computing modules.
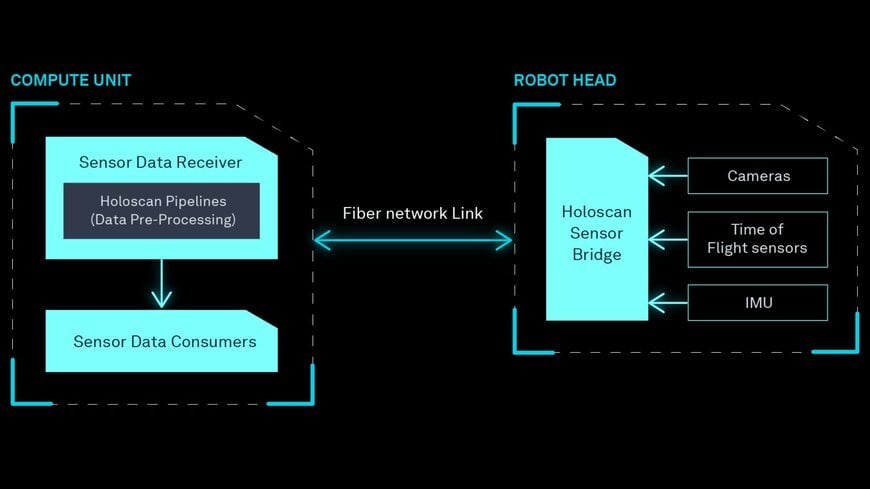
Figure 1. Overview of Hexagon Robotics’ sensor-processing architecture, integrating NVIDIA Holoscan Sensor Bridge.
Mechanical and Computational Bottlenecks in Humanoid Perception
Multipurpose robotic operation relies on real-time sensor fusion combining diverse streams, including RGB video feeds, depth data, and inertial measurement unit readings. In earlier design iterations, Hexagon Robotics operated dual computing nodes interconnected over ROS 2 to manage simultaneous localization and mapping alongside AI-based feature detection. Image transformations, neural network inference, and classical computer vision algorithms ran across GStreamer pipelines using NVIDIA DeepStream plugins.
This distributed arrangement created operational and physical limitations. Connecting sensors via standard MIPI interfaces required 12 fixed ports split across both compute units, forcing inter-unit data transfers that introduced latency. Furthermore, running multi-conductor wiring harnesses through the robot's rotating neck mechanism imposed severe mechanical routing constraints, increasing wear and limiting rotational mobility.
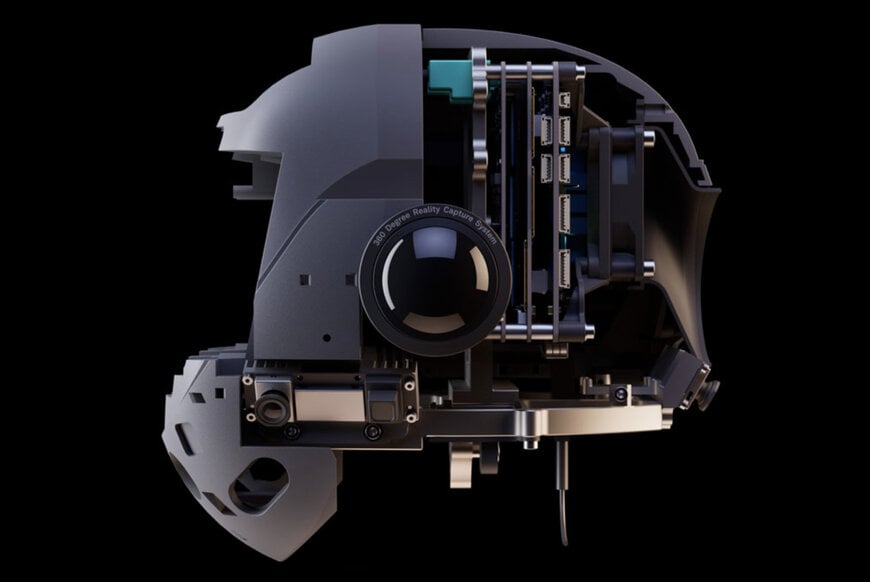
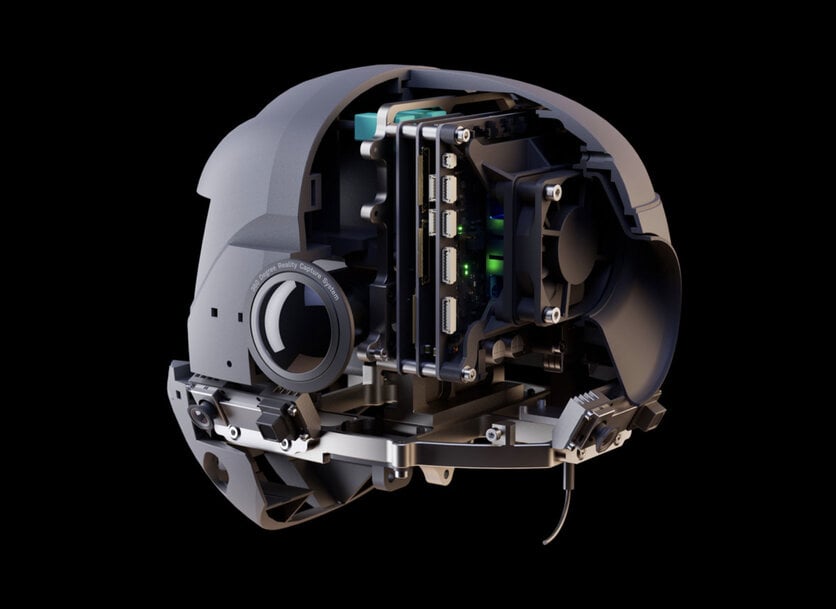
Figure 2. AEON’s head, housing the sensors and hardware used to capture and synchronise data for perception.
FPGA Bridge and High-Throughput Optical Transport
To resolve physical interconnect limits and latency overhead, Hexagon Robotics engineered a unified hardware-software sensor bridge. The architecture incorporates a custom data-processing board paired with FPGA logic configured to synchronize frame capture across cameras and depth sensors, ensuring precise temporal alignment across all sensing modalities.
NVIDIA Holoscan functions as the central runtime environment, managing sensor pipeline execution and integrating Holoscan Sensor Bridge modules to handle inertial measurement unit telemetry and deterministic data transport. Rather than routing individual copper MIPI lanes through articulated joints, the synchronized sensor payloads transition onto an optical fiber using an NVIDIA IP core.
The optical link terminates at an NVIDIA Jetson Thor computing module through a custom receiver board. Ingress traffic is processed directly via the platform's hardware-accelerated multi-gigabit Ethernet interface. This layout accommodates up to 100 Gbit/s of peak network bandwidth while eliminating unnecessary buffer copying operations within the measured transmission path.
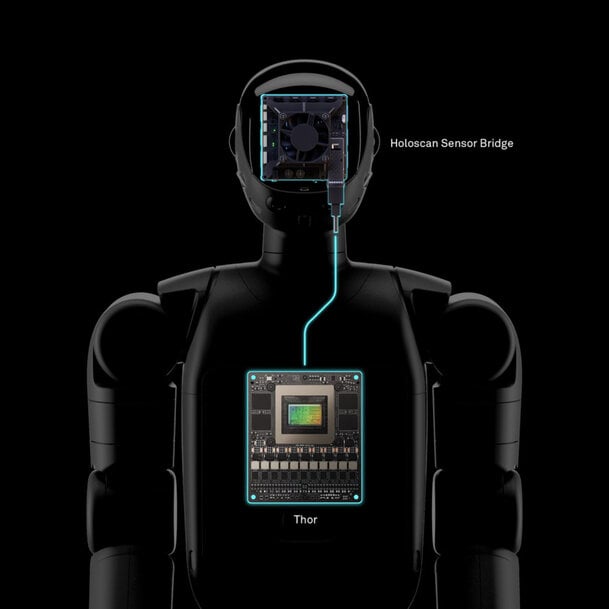
Figure 3. Sensor data travels from AEON’s head to the NVIDIA Jetson Thor compute module through a fibre-optic connection, simplifying cabling through the robot’s rotating neck.
Compute Resource Optimization for Spatial Intelligence
Relieving the central processors from low-level data ingestion yields measurable performance gains across AEON's onboard architecture. Offloading sensor ingest to dedicated interface hardware reduces CPU consumption to less than 1% per sensor stream. Optical ingestion removes camera data processing entirely from the graphics processing unit, leaving only minor GPU computation requirements for time-of-flight depth processing.
Preserving primary compute capacity allows Hexagon Robotics to allocate central GPU resources directly to high-level spatial AI, dynamic object classification, and motion planning routines. Because Jetson Thor utilizes networked interfaces, the engineering team can expand sensor arrays or integrate networking switches to support added modalities without provisioning secondary central processing units.
Additional Context:
This section details technical specifications and competitive benchmarking not included in the original product announcement.
The transition from localized MIPI buses to high-bandwidth network protocols aligns with a broader shift in high-performance robotics toward software-defined sensor pipelines. Industrial humanoid architectures frequently struggle with the trade-offs between distributed microcontrollers and centralized high-performance computing, particularly when routing high-bandwidth MIPI or USB 3.0 lines across articulated joints like robotic necks and multi-axis gimbals.
Standard MIPI CSI-2 transmission is restricted by trace and cable lengths (typically under 30 centimeters without active redrivers) and requires point-to-point connections, making harness routing through rotary joints a common failure point. By encapsulating serialized camera and depth feeds into Ethernet packets transported over fiber optics, the architecture bypasses electromagnetic interference risks and mechanical bending limits associated with copper wire bundles.
In competitive benchmark architectures, humanoid systems often manage perception pipelines via separate edge vision processors or industrial PCs running ROS 2 nodes over standard copper Gigabit Ethernet. Such arrangements often consume considerable host CPU overhead managing serialization, deserialization, and memory copies (IPC) across distinct processing blocks. Leveraging dedicated FPGA preprocessing combined with hardware-accelerated network interfaces provides zero-copy sensor delivery directly into GPU memory via direct memory access mechanisms, representing a standardized design pattern for low-latency autonomous operations requiring continuous environmental mapping.
Edited by Natania Lyngdoh, Induportals editor, with AI assistance.
www.robotics.hexagon.com